







How Can Ecommerce Brands Use Returns Data to Reduce Reverse Logistics Costs?


Ready to delight customers after checkout?
Trusted by 600+ brands
In this blog
TL;DR – Summary
Reverse logistics costs are the silent margin killer in ecommerce, with each return costing up to 3–4x the refund value once labor, markdowns, and carrying costs are counted. A structured four-stage data program turns that hidden cost into a controllable, measurable lever.
- True Cost of Returns – Hidden costs dwarf the visible refund amount
- Reason Code Accuracy – Data quality gate every other KPI depends on
- Days to Disposition – Speed cuts markdown risk and carrying cost
- Return Rate by SKU – Isolates avoidable returns from structural ones
- Resale Recovery Rate – Maximizes value rescued from each returned unit
- Four-Stage Data Program – Maps prevention, speed, and recovery systematically
Introduction
Using returns data to reduce reverse logistics costs starts with one uncomfortable number. A single ecommerce return costs between $10 and $65 in direct processing, and the true cost runs three to four times the refund amount once inbound shipping, labor, inspection, markdown risk, and carrying cost are counted.
If you own the P&L for reverse logistics, as a supply chain manager, director of operations, or head of ecommerce, you already know returns do not get cheaper by ignoring them.
The structural problem is that online return rates now sit at 19.3 percent, per the NRF and Happy Returns 2025 Retail Returns Landscape report, close to double the rate physical stores see, and that gap is not closing.
This article maps a four-stage returns data program, moving from initiation to receipt to inspection to disposition, and shows how each stage unlocks one of three cost levers, which are prevention, processing speed, and value recovery.
What a return actually costs, beyond the shipping label
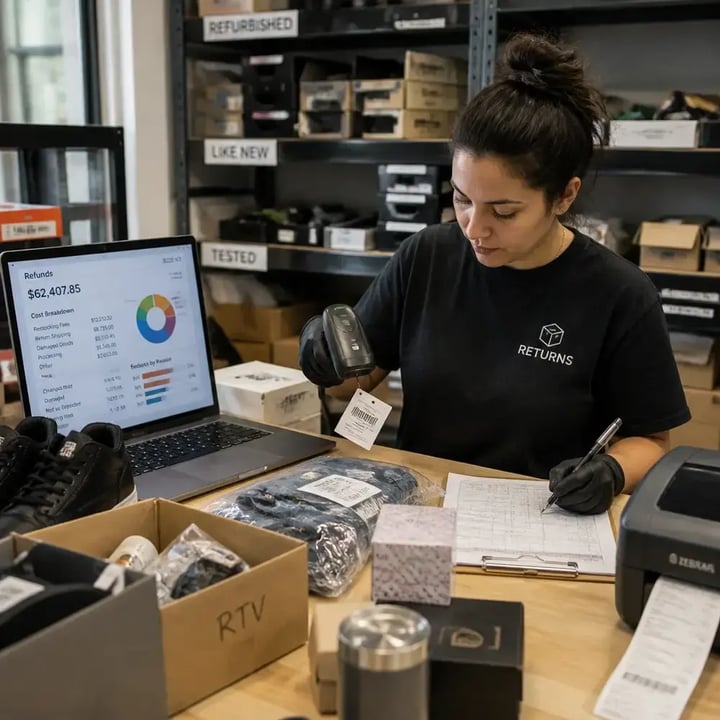
The refund is the visible cost and the rest of the stack is larger and mostly hidden. Inbound transportation moves the unit back to the warehouse. Receiving labor scans and opens it, inspection and grading labor assesses its condition, and repackaging restores it to sellable presentation.
Markdown risk grows with every day the item waits for a disposition decision. Fraud exposure sits on top for a share of returns, and inventory carrying cost accrues through the disposition lag. Add these together and reverse logistics can cost two to three times what forward fulfillment costs per unit.
For example, a $60 return on a $120 apparel item can generate $80 to $90 in total reverse logistics cost before the item is resold at roughly $40. That is a net loss of $50 to $60 on what looked like a simple refund.
The disposition decision depends on knowing the item's condition and recovery value in each channel, which is exactly what structured data supplies at inspection. That is why speed and accuracy on this one call govern everything downstream, from markdown to carrying cost.
Why are return rates structurally higher in ecommerce
Digital channels create expectation gaps such as sizing issues, defects, broken parts and the customer not being able to touch, try, or see the product before it arrives.
Apparel and footwear also see bracket buying, where shoppers order several sizes intending to return most of them. Competitive pressure and customer expectations have led many brands to offer generous return windows, which can further increase return volumes.
Online return rates run at 19.3 percent against roughly 10 percent in stores. Much of that gap is structural, driven by the fact that shoppers can't try before they buy and often bracket sizes on purpose, and no amount of policy tightening removes it. The returns worth targeting are the avoidable ones, from wrong sizes shipped to misleading descriptions, and cutting them starts with telling the two apart.
Reverse logistics KPIs every operations team should track
Without defined KPIs, returns analytics produces reports no one acts on. These are the eight metrics that connect data to decisions.
Here is the formatted table with all your reverse logistics KPIs organized clearly:
| KPI | What It Measures | Benchmark | Data Source | Cost Reduction Lever |
| Cost per return | Total reverse logistics cost per unit processed | $10 to $65 (varies by category) | RMS + WMS + Finance | Baseline for all ROI calculations |
| Return rate by SKU / category | Percent of units sold returned per product line | Under 10% hard goods; under 20% apparel | RMS + OMS | Identifies avoidable return concentration |
| Days to disposition | Time from return receipt to restock or liquidation decision | Under 3 days (best in class) | WMS | Reduces carrying cost and markdown risk |
| Resale recovery rate | Percent of return value recovered via resale by condition grade | 60 to 80% like-new; 20 to 40% damaged | WMS + resale channel | Optimizes value recovery routing |
| Refurbishment rate | Percent of returned units entering repair or refurb vs. liquidation | Category dependent | WMS + QC system | Signals inspection accuracy and routing |
| Return fraud rate | Percent of returns flagged as fraudulent or policy-abused | 9% of returns (NRF 2025) | RMS + fraud tool | Reduces refund leakage |
| Time to restock | Days from receipt to available inventory for restockable units | Under 24 hours (best in class) | WMS + OMS | Reduces lost-sale and carrying cost |
| Reason code accuracy rate | Percent of returns with a valid, mapped reason code | Over 90% target | Returns portal + WMS | Data quality gate for every other KPI |
Reason code accuracy looks like clerical housekeeping but functions as the data quality gate that decides whether every other KPI in this table can be trusted.
Cost per return and the raw return rate survive a bad code, since they are counts, but the moment you break return rate out by SKU or category, or route a unit through days to disposition, resale recovery rate, and refurbishment rate, the code becomes the input those metrics read from.
Miss the 90 percent target and your avoidable-return concentration and your disposition mix are both built on guesses, and a return miscoded "changed mind" instead of "defective" lands in the wrong disposition bin and understates your defect rate at the same time. You can fix the gate first and then instrument the rest.
How to use returns data to reduce reverse logistics costs: a four-stage framework
Six data-driven actions to reduce reverse logistics costs:
-
Track return reason codes by SKU to identify and eliminate avoidable returns at the source.
-
Use condition-grade data from inspection to automate disposition routing decisions.
-
Monitor days to disposition to reduce inventory carrying cost on returned units.
-
Connect reason code trends to product page updates that fix upstream listing issues.
-
Flag high-return SKUs for supplier scorecards and procurement review.
-
Route returned inventory to the highest-value resale channel using recovery rate data.
The six actions above map onto four stages of the return lifecycle. Each stage captures a distinct dataset, and each dataset controls a different cost lever.
Stage 1. Return initiation data: what to capture when the customer requests a return
Capture the customer-selected return reason code, product SKU, order channel, customer segment or CLTV tier, and the requested return method. This is the only stage where you record the customer’s stated reason before inspection, which is what separates avoidable returns, such as sizing and expectation mismatch, from structural ones, such as defects and carrier damage.
The cost lever here is policy segmentation. High-CLTV customers can be routed to instant exchanges while fraud-risk profiles get added friction, which cuts refund leakage without punishing loyal buyers.
Stage 2. Receipt and condition-grading data: what to capture when the return arrives
Record the condition grade on a documented A to D scale, whether the received SKU matches what was expected, the inbound carrier and transit time, and a photo documentation flag. Condition grade is the primary input to disposition routing.
Without standardized grading, disposition happens ad hoc and recovery rates swing unpredictably. The cost lever is automation. Grade A goes straight to restock, grade B enters the refurb queue, grade C routes to liquidation, and grade D flags for vendor chargeback review.
Stage 3. Inspection and disposition data, the highest-impact stage
Capture the final disposition decision, processing time in hours, labor cost per unit, the disposition channel selected, and projected recovery value.
This is where cost per return is either contained or allowed to compound, because every extra day in the inspection queue adds carrying cost and markdown risk.
Disposition data feeds days to disposition, resale recovery rate, and refurbishment rate at once. Operations teams that instrument all four stages can target cost-per-return reductions of 15 to 25 percent over two quarters, because the gains at each stage compound on the one before it.
Stage 4. Post-disposition analytics, the feedback loop that reduces future returns
Track return rate trend by SKU over rolling 30, 60, and 90 day windows, cluster reason codes by product attribute such as size, color, and material, and record recovery value by condition grade and channel. This stage converts reverse logistics from a cost center into a prevention system.
The data feeds three downstream systems. Product page updates close expectation-gap returns, supplier scorecards trigger accountability conversations, and demand forecasting pre-positions inventory near high-return segments. McKinsey’s analysis of modernizing reverse logistics with AI points to the same move, using predictive analytics to flag high-return product segments and adjust pricing, bundling, or incentives before the returns build.
The missing link: connecting returns data to supplier scorecards
Most returns analytics programs stop at the warehouse door. The highest-performing supply chain teams take returns data one step further, back to the vendor. When reason codes and condition grades show a consistent defect pattern on a specific SKU, that data becomes a supplier chargeback trigger, a quality escalation input, or a contract renewal lever.
This is standard practice in retail buying, yet it is absent from almost all ecommerce returns content. The data handoff flow runs in one direction. The reason code feeds the SKU-level defect rate, that defect rate feeds a vendor scorecard flag, and the flag feeds procurement review.
Consider a supplier whose apparel SKU shows a 28 percent return rate over 90 days with fabric quality as the dominant reason code. That is not a returns problem, it is a procurement problem, and returns data is what makes it visible. This is also where returns data earns a seat in quarterly business reviews rather than sitting quietly as a post-purchase cost line.
How ClickPost builds a returns intelligence layer across your existing systems
ClickPost’s role is to make returns data operational at each stage without replacing the systems already running your warehouse.
At initiation, ClickPost’s Returns product applies policy segmentation by customer persona, routing high-CLTV customers to instant exchange flows and applying returns protection rules that cut refund leakage without adding friction for good customers.
During processing, ClickPost’s order editing capability lets customers fix sizing or address errors before a return is ever initiated, removing a measurable share of avoidable returns before they enter the pipeline. On the post-purchase side, ClickPost’s tracking and WISMO reduction products cut inbound where-is-my-return contact, a hidden labor cost that most competing content ignores entirely.
For revenue recovery, ClickPost’s post-purchase upsells and exchanges functionality turns return-intent moments into retention events, keeping a meaningful share of revenue that would otherwise leave as a refund.
For intelligence, ClickPost’s customer segmentation data connects return behavior to CLTV, purchase frequency, and channel, giving the head of ecommerce a cross-functional view to turn returns data into merchandising and marketing decisions.
Together these products form a returns intelligence layer that converts returns from a reverse logistics cost center into a margin recovery operation.
Is your returns data infrastructure ready? A self-audit checklist
Run through these eight diagnostics. Each is a yes or no.
-
Are return reason codes standardized across your returns portal, WMS, and ERP, using one taxonomy in all three?
-
Is condition grading applied consistently at receiving, on a documented A to D scale that every warehouse staffer follows?
-
Can you pull return rate by SKU for any rolling 30, 60, or 90 day window without a manual export?
-
Do you track days to disposition as a live operational KPI rather than a monthly finance report?
-
Is your returns data connected to your demand forecasting or inventory replenishment system?
-
Do high-return-rate SKUs automatically trigger a review in your supplier scorecard process?
-
Can your team separate avoidable returns from structural ones inside the data?
-
Is your reason code accuracy rate above 90 percent, meaning fewer than one in ten returns carries an invalid or incomplete code?
If you answered no to three or more, your returns data program is operating at Level 1, reactive and manual. The sections above outline the path to Level 3.
From cost line to operational intelligence
Returns data functions as an operational system that reduces cost at prevention, processing, and recovery at the same time, well beyond any reporting exercise. Three starting points give a supply chain manager traction this quarter.
First, audit your reason code taxonomy across the returns portal, WMS, and ERP, and make all three agree. Second, add days to disposition to your live operational dashboard instead of leaving it in a monthly finance report. Third, pull return rate by SKU for the last 90 days and identify the ten SKUs driving the most return concentration. As NRF’s Katherine Cullen put it, “returns are no longer the end point of a transaction.”
The best operations do not simply manage returns, they use returns data to prevent the unnecessary ones, process the unavoidable ones faster, and recover more value from every unit that comes back.
FAQs
What data should ecommerce brands collect from product returns?
Collect the return reason code, product SKU, customer CLTV tier, order channel, condition grade at receipt, disposition decision, and time from receipt to disposition. Those seven fields are the minimum viable dataset for a returns analytics program, because they connect why a return happened to what it cost and what was recovered.
How do you calculate the true cost of reverse logistics?
Add inbound shipping, receiving labor, inspection labor, repackaging, markdown risk on delayed inventory, fraud exposure, and carrying cost during the disposition lag. The true cost typically runs three to four times the refund amount, ranging from $10 to $65 per return in direct costs alone.
What are return reason codes and how do they reduce logistics costs?
Return reason codes are customer-selected or warehouse-assigned tags that categorize why a return happened, such as wrong size, not as described, or arrived damaged. They cut costs by identifying which returns are avoidable, which then enables product page fixes, supplier accountability, and policy adjustments that lower future volume.
How can predictive analytics reduce ecommerce return rates?
By flagging high-return-risk orders before they ship. Identifying SKU and customer-segment combinations with historically high return rates lets operations teams trigger proactive interventions such as fit guidance, sizing alerts, and product content updates that reduce return initiation at the source.
What KPIs should supply chain managers track for reverse logistics?
The eight core KPIs are cost per return, return rate by SKU, days to disposition, resale recovery rate, refurbishment rate, return fraud rate, time to restock, and reason code accuracy rate. The KPI table above lists benchmarks and data sources for each one.
How does returns data improve inventory management?
Returns data feeds demand forecasting by revealing which SKUs are net-negative inventory, sold and returned at high rates. It also pre-positions restockable inventory closer to high-return-rate geographies and reduces overstock driven by returns lag.
When does it make financial sense to use a 3PL for reverse logistics?
Outsource when your cost per return exceeds the 3PL’s per-unit processing rate and you lack the volume to justify dedicated reverse logistics infrastructure. As a rule of thumb, brands processing fewer than 500 returns per week often see savings from 3PL consolidation.
How do you build a returns data program that integrates with your WMS and ERP?
Start by standardizing reason code taxonomy across your returns portal, WMS, and ERP so all three systems use the same codes. Then set up API connections or flat-file exports that feed a central returns dashboard tracking the eight KPIs above.
How do return reason codes connect to vendor accountability?
When reason code data shows a recurring defect pattern on a supplier’s SKU, such as a persistent fabric-quality code above 15 percent of returns, that data can route to your vendor scorecard as a chargeback trigger or contract review input, shifting the cost consequence upstream.
What is the ROI timeline for a returns data investment?
Brands that implement standardized reason codes, condition grading, and disposition KPI tracking typically see measurable cost-per-return reduction within two quarters. Full payback usually occurs within six to nine months, depending on return volume and baseline data maturity.


We use cookies to keep the site working, understand usage, and improve your experience. Learn more
Always active for essential site performance and security.
Enables anonymous usage analysis to refine our services.
Used to present relevant promotions and advertising.